In .Net memory access is safe by default. This means that every time you access an array item the index is checked against the length of the array. In this post I explore how you can speed up plain old array access 18%-34% by convincing the compiler it can skip some checks.
I compile the C# code down to X64 native code and analyze that, then run some benchmarks to see if my assumptions are correct.
Bounds checking
To demonstrate the bounds check, lets start off with a simple application that iterates an array:
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IteratePublicArray() {
 for(var i = 0; i < PublicArray.Length; i++)
 Sum += PublicArray[i];
 }
}
The x64 JIT Asm output of this is:
L0000: sub rsp, 0x28
 ; Clear register eax
 L0004: xor eax, eax
 ; Check if array length > 0
 L0006: mov rdx, [rcx+8]
 L000a: cmp dword ptr [rdx+8], 0
 L000e: jle short L002d
 ; START OF LOOP
 L0010: mov r8, rdx
 ; Bounds check
 L0013: cmp eax, [r8+8]
 L0017: jae short L0032
 ; Add to sum
 L0019: movsxd r9, eax
 L001c: movzx r8d, byte ptr [r8+r9+0x10]
 L0022: add [rcx+0x10], r8d
 ; Increase i and jump back to start of loop
 L0026: inc eax
 L0028: cmp [rdx+8], eax
 L002b: jg short L0010
 ; END OF LOOP
 L002d: add rsp, 0x28
 L0031: ret
 ; throw IndexOutOfRangeException
 L0032: call 0x00007ff8b097f6a0
 L0037: int3
You don’t need to understand assembly code, I will explain.
In L0013 and L0017 there is a bounds-check inside the loop. This is done by comparing the index we are accessing to the size of the array. In 64-bit mode the size of an array is stored 8 bytes into the object memory right after Method Table, so pointer address+8 or r8+8.

Proof
A cool thing about compilers is that they can optimize the code a lot. But to optimize it, they need to be able to prove that there are no side effects.
So what if compiler was able to prove that we will never go outside of the bounds of the array? Then it could skip the bounds check. Lets try.
First of, an array can’t be resized. And we already guarantee that we won’t exceed the bounds of the array in the for-loop “i < PublicArray.Length”. The problem is that we are using a shared (public) variable (not in local scope), so it could be replaced at any point (by our code/other threads/callbacks). Therefore bounds check has to be performed on every access to the array.
If we make a local copy of PublicArray then the compiler should be able to prove that we will never exceed the bounds of the array, since the array pointer can’t be updated.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IterateLocalCopyArray()
 {
 var pa = PublicArray;
 for (var i = 0; i < pa.Length; i++)
 Sum += pa[i];
 }
}
Gives us the X64 Jit ASM output:
L0000: mov rax, [rcx+8]
 L0004: xor edx, edx
 L0006: mov r8d, [rax+8]
 L000a: test r8d, r8d
 L000d: jle short L0023
 ; START OF LOOP
 L000f: movsxd r9, edx
 L0012: movzx r9d, byte ptr [rax+r9+0x10]
 L0018: add [rcx+0x10], r9d
 L001c: inc edx
 L001e: cmp r8d, edx
 L0021: jg short L000f
 ; END OF LOOP
 L0023: ret
Success. Immediately we can see that we went from 18 to 12 instructions. The compiler was able to prove that we will not exceed the bounds of this array, which allowed it to skip the bounds checks.
Fixed raw pointer
There is another way to ensure no bounds check is being made, and that is by using a fixed statement and do reference arithmetic. This is unsafe, because you can read/write outside of the bounds of the array. Fixed statements has a scope, you can use GCHandle to create a long lived pin. But note that pinned objects has a cost for the garbage collector unless you are using the new Pinned Object Heap in .NET 5 or later.
Note that we are using Public.Array.Length here now. We’ll get back to optimizing that in the section on Span.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public unsafe void IterateLocalCopyUnsafeArray()
 {
 fixed (byte* pa = &PublicArray[0])
 {
 for (var i = 0; i < PublicArray.Length; i++)
 Sum = pa[i];
 }
 }
}
Which gives us x64 JIT Asm:
L0000: sub rsp, 0x28
 L0004: xor eax, eax
 L0006: mov [rsp+0x20], rax
 L000b: mov rax, [rcx+8]
 L000f: mov rdx, rax
 L0012: cmp dword ptr [rdx+8], 0
 L0016: jbe short L0050
 L0018: add rdx, 0x10
 L001c: mov [rsp+0x20], rdx
 L0021: mov rdx, [rsp+0x20]
 L0026: xor r8d, r8d
 L0029: cmp dword ptr [rax+8], 0
 L002d: jle short L0044
 // START OF LOOP
 L002f: movsxd r9, r8d
 L0032: movzx r9d, byte ptr [rdx+r9]
 L0037: add [rcx+0x10], r9d
 L003b: inc r8d
 L003e: cmp [rax+8], r8d
 L0042: jg short L002f
 // END OF LOOP
 L0044: xor eax, eax
 L0046: mov [rsp+0x20], rax
 L004b: add rsp, 0x28
 L004f: ret
 // throw IndexOutOfRangeException
 L0050: call 0x00007ff8b097f6a0
 L0055: int3
Benchmark
So lets run these through some benchmarks.
We test two different array sizes, one small that fits inside L1 cache and one larger that effectively purges the cache.
1024 bytes (1KB)
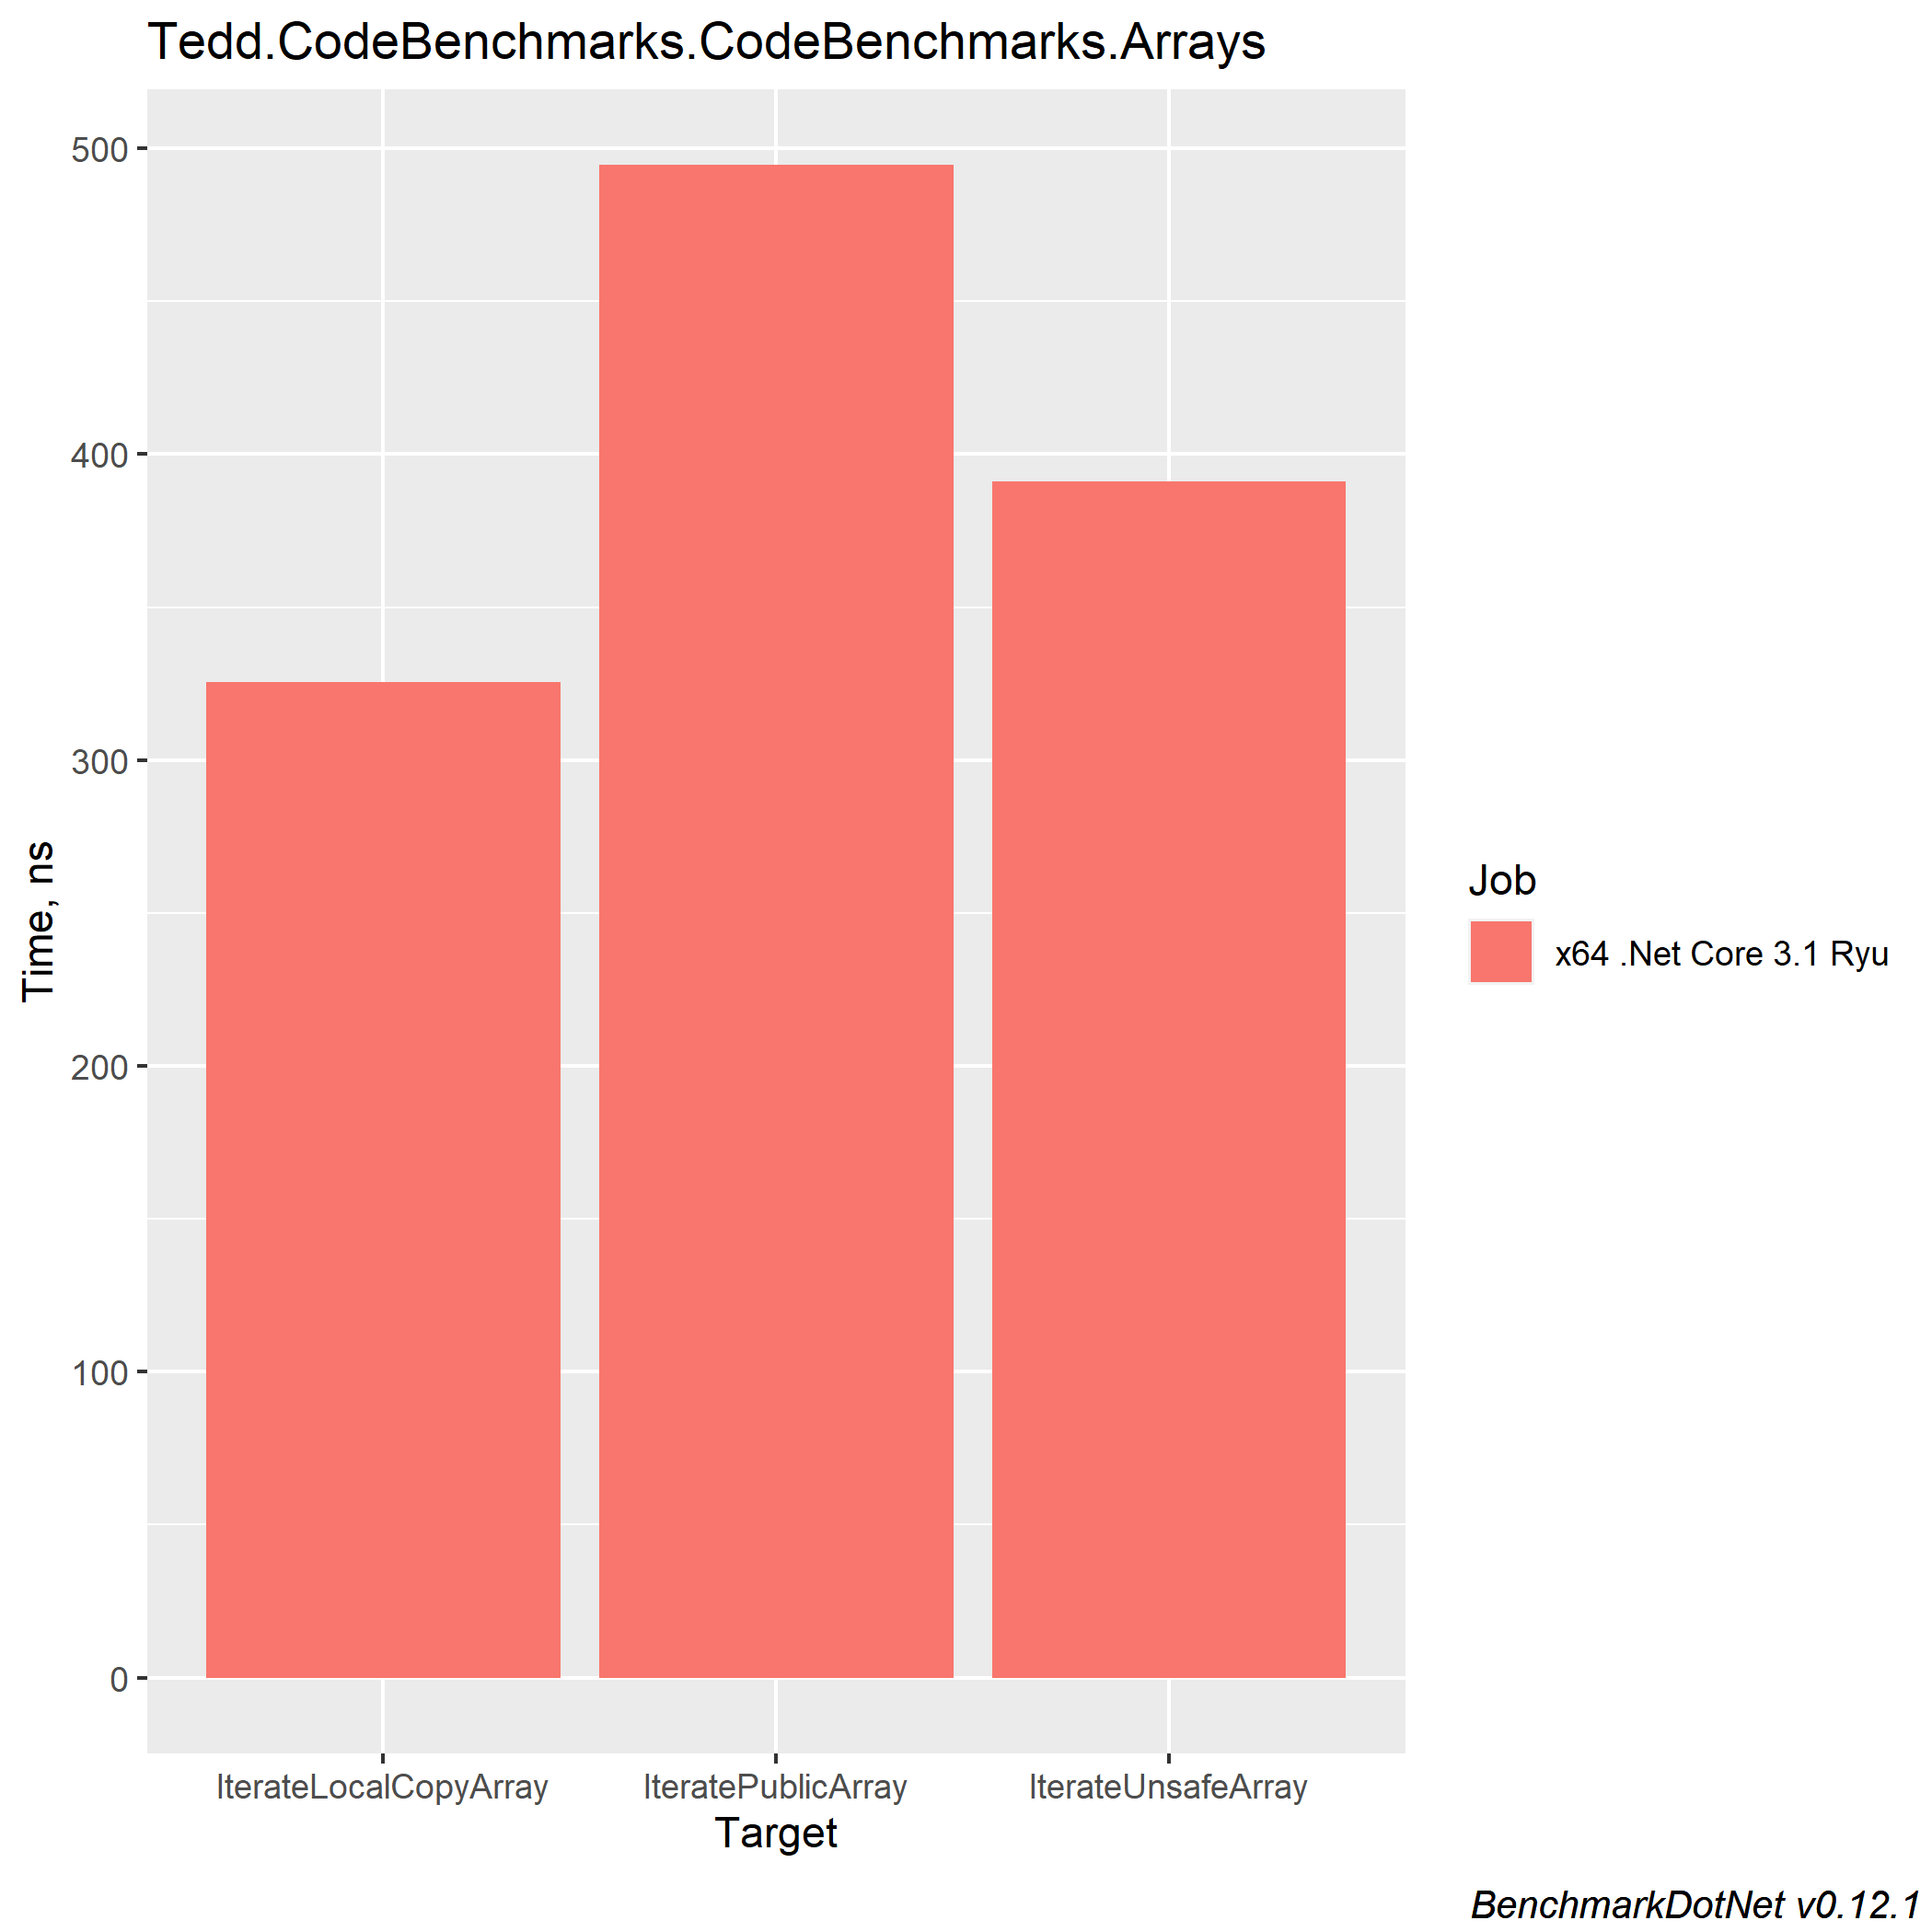
Using a local copy of the variable gives 34% performance gain.
1024 MB (1GB)
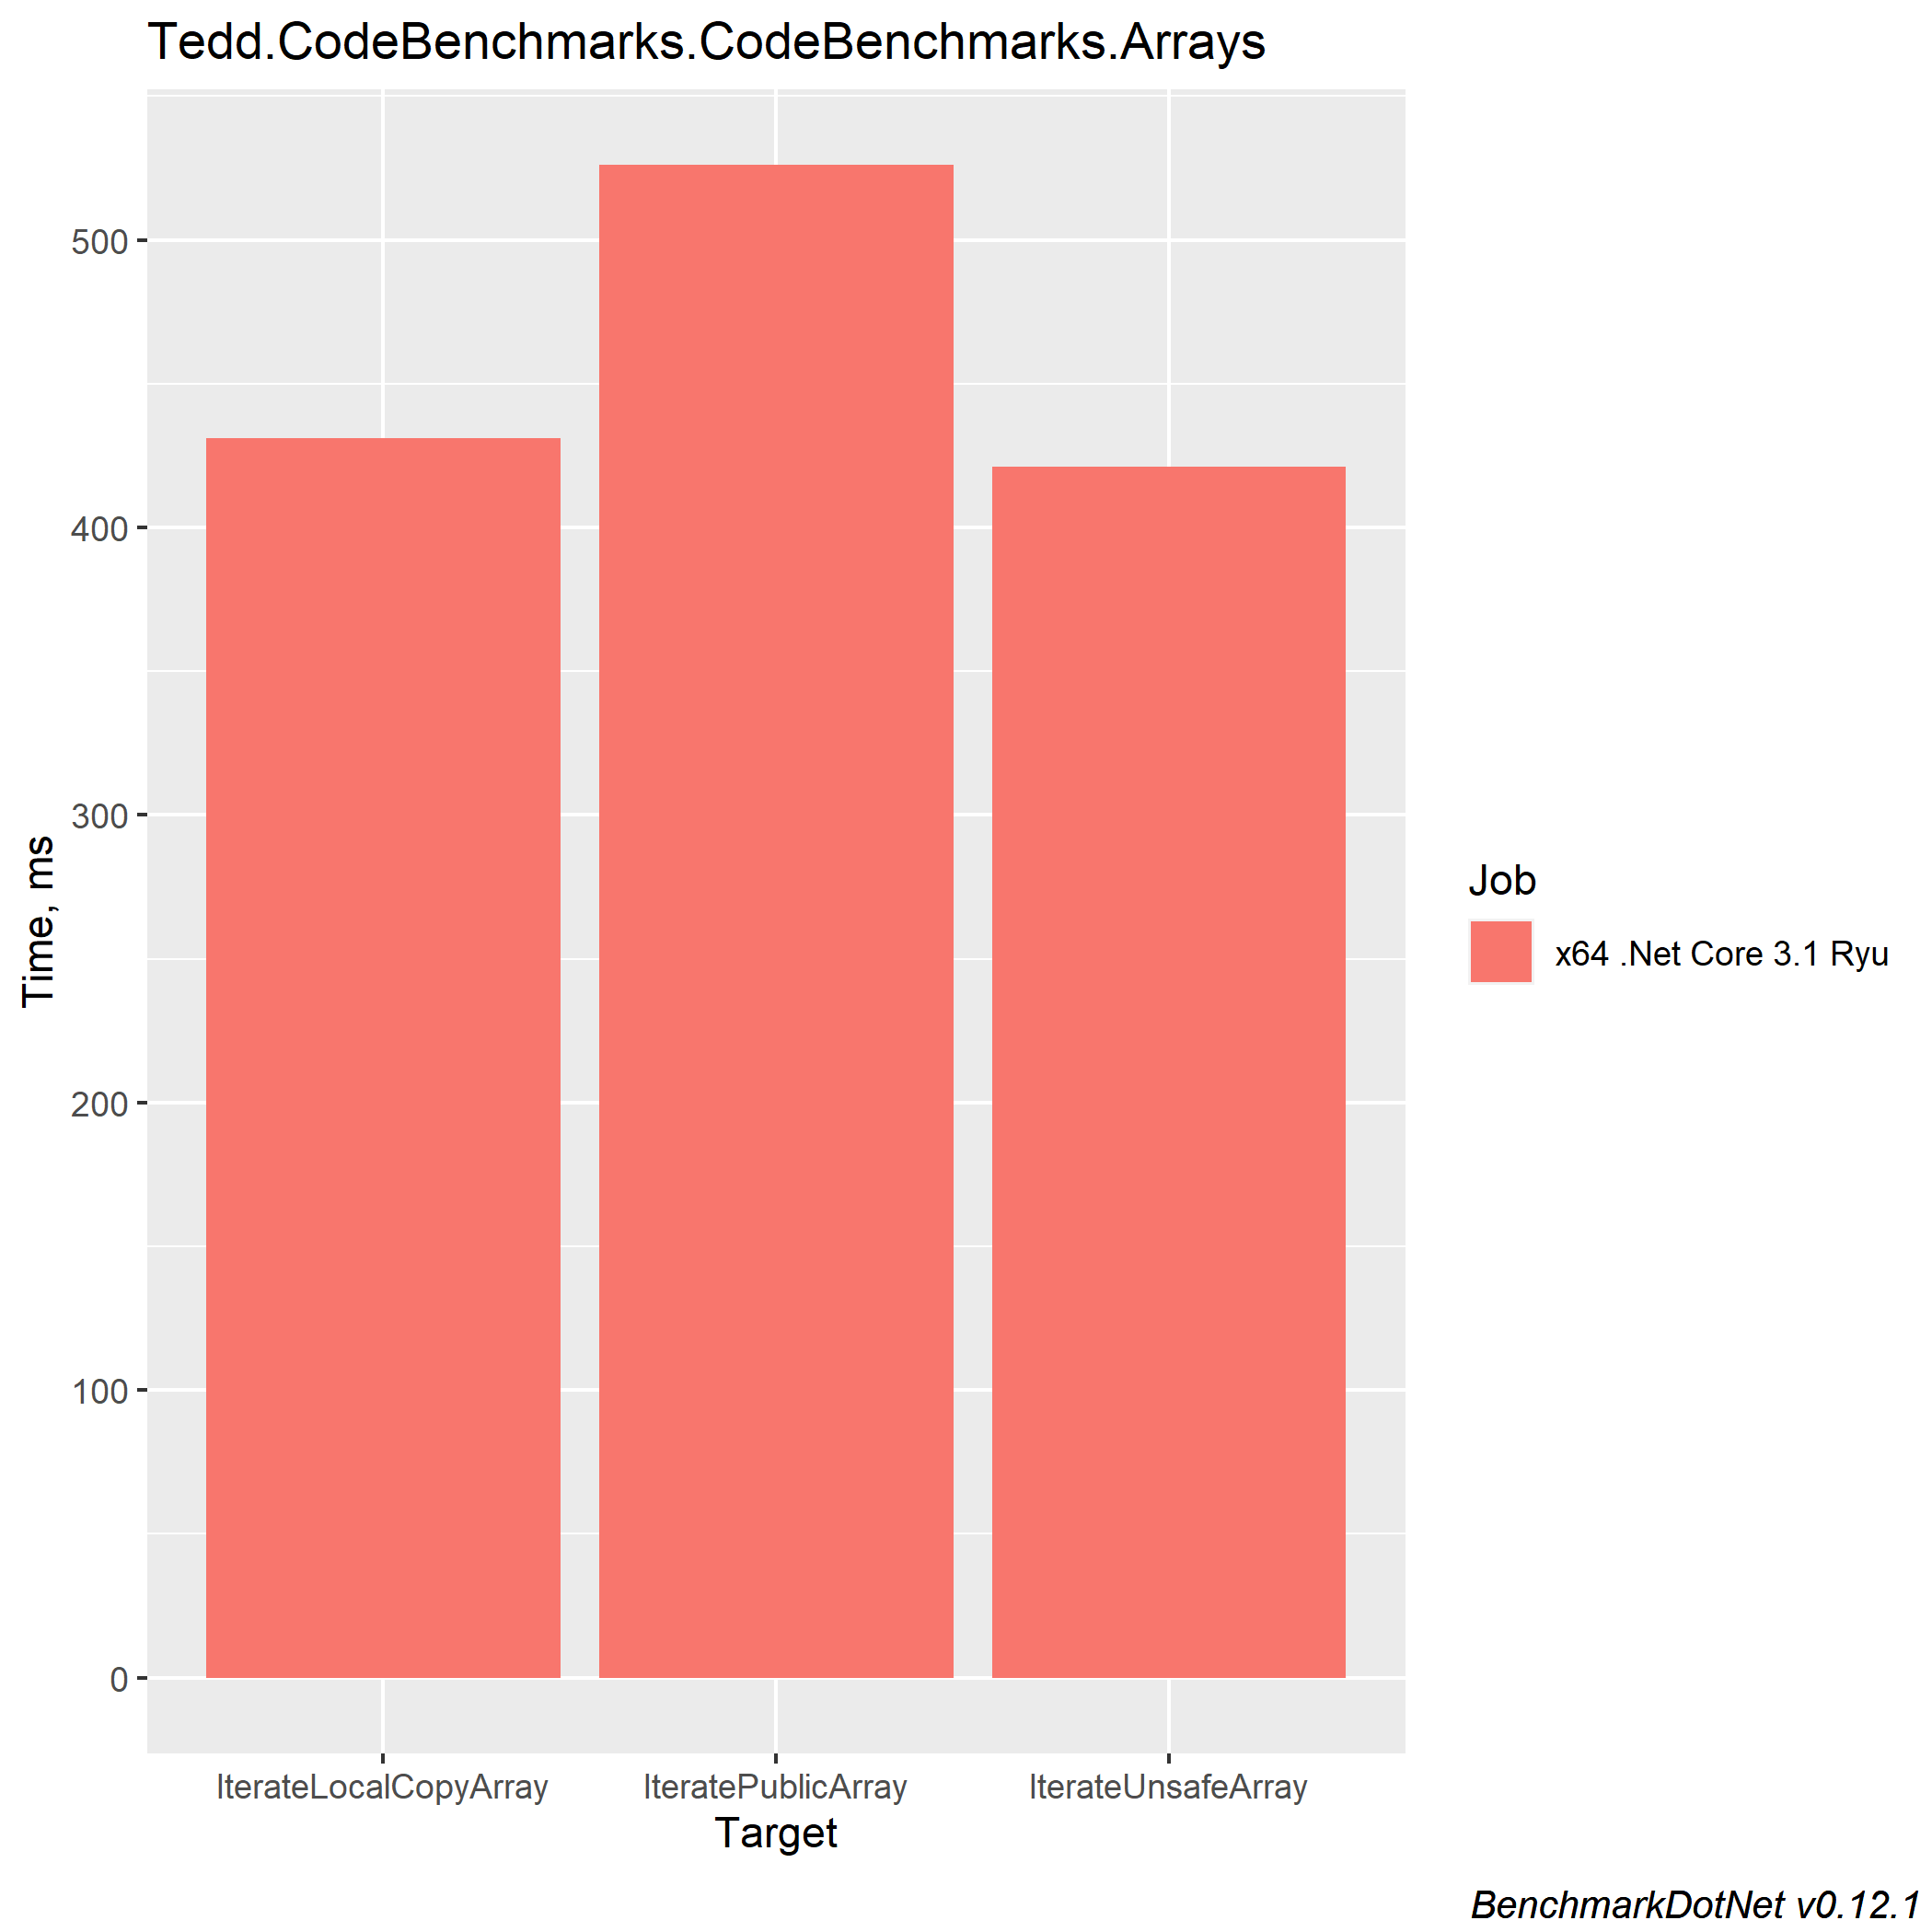
On a larger array we can see that the overhead of setting up fixed pointer is negligible, and performance is slightly better than a local copy.
There is some overhead in accessing main memory, so the relative percentage is lower.
Unsafe array 20% performance gain.
Local copy array 18% performance gain.
Foreach
So far we have used for. Foreach seemingly works differently with iterators and all that. Lets look at the same method using foreach:
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void ForEachLocalCopy()
 {
 var pa = PublicArray;
 foreach (var t in pa)
 Sum += t;
 }
}
Compiles to 100% identical assembly code as its for counterpart.
L0000: mov rax, [rcx+8]
 L0004: xor edx, edx
 L0006: mov r8d, [rax+8]
 L000a: test r8d, r8d
 L000d: jle short L0023
 L000f: movsxd r9, edx
 L0012: movzx r9d, byte ptr [rax+r9+0x10]
 L0018: add [rcx+0x10], r9d
 L001c: inc edx
 L001e: cmp r8d, edx
 L0021: jg short L000f
 L0023: ret
We see the same with foreach on public array, it compiles to the same assembly code as its for counterpart and hence has bounds checks.
Span
Span is a structure that is stored on the stack. It can be used to access both managed and unmanaged memory.
If you do not use .Length-property of the array you are looping over, the bounds check will be present.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IterateLocalCopyArrayN()
 {
 var pa = PublicArray;
 for (var i = 0; i < 10; i++)
 {
 Sum += pa[i];
 }
 }
}
Compiles to:
L0000: sub rsp, 0x28
 L0004: mov rax, [rcx+8]
 L0008: xor edx, edx
 L000a: mov r8d, [rax+8]
 // START OF LOOP
 // Bounds check
 L000e: cmp edx, r8d
 L0011: jae short L002c
 // Add to sum
 L0013: movsxd r9, edx
 L0016: movzx r9d, byte ptr [rax+r9+0x10]
 L001c: add [rcx+0x10], r9d
 // Increase i and jump back to start of loop
 L0020: inc edx
 L0022: cmp edx, 0xa
 L0025: jl short L000e
 // END OF LOOP
 L0027: add rsp, 0x28
 L002b: ret
 // throw IndexOutOfRangeException
 L002c: call 0x00007ff8b097f6a0
 L0031: int3
One way to bypass this is to use Span. Span has the same constraints for optimization and will still have the bounds check, but you can set the bounds to the desired size and have the for-loop iterate on that. In this case the bounds only needs to be checked once.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IterateLocalSpan()
 {
 var pa = new Span<byte>(PublicArray, 0, 5);
 for (var i = 0; i < pa.Length; i++)
 {
 Sum += pa[i];
 }
 }
}
Compiles to:
L0000: sub rsp, 0x28
 L0004: mov rax, [rcx+8]
 L0008: test rax, rax
 L000b: je short L0034
 // Bounds check that array length is >= 5
 L000d: mov edx, [rax+8]
 L0010: cmp rdx, 5
 L0014: jb short L003a
 L0016: add rax, 0x10
 L001a: xor edx, edx
 // START OF LOOP
 L001c: movsxd r8, edx
 L001f: movzx r8d, byte ptr [rax+r8]
 L0024: add [rcx+0x10], r8d
 // Increase i and jump back to start of loop
 L0028: inc edx
 L002a: cmp edx, 5
 L002d: jl short L001c
 // END OF LOOP
 L002f: add rsp, 0x28
 L0033: ret
 L0034: call System.ThrowHelper.ThrowArgumentOutOfRangeException()
 L0039: int3
 L003a: call System.ThrowHelper.ThrowArgumentOutOfRangeException()
 L003f: int3
Conclusion
In certain cases the compiler can remove the bounds checks when accessing arrays. This leads to around 18%-34% performance increase in accessing the array itself. Alternatively you could do unsafe reference arithmetic using fixed statement and achieve the same performance.
Condition: You access a local variable (pointing to the array) using a for-statement that caps at the arrays length.
Bonus: You can create these conditions using Span.
So this:
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IterateLocalCopyArray()
 {
 var pa = PublicArray;
 for (var i = 0; i < pa.Length; i++)
 Sum += pa[i];
 }
}
Is 18%-34% faster than this:
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IteratePublicArray() {
 for(var i = 0; i < PublicArray.Length; i++)
 Sum += PublicArray[i];
 }
}
On larger arrays accessing memory directly as pointer is about 20% faster.
Accessing single indexes
If we try to access the array by an index, the check is back.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IndexedAccess()
 {
 var pa = PublicArray;
 Sum += pa[5];
 Sum += pa[6];
 }
}
Gives us two bounds checks:
L0000: sub rsp, 0x28
 L0004: mov rax, [rcx+8]
 L0008: mov edx, [rcx+0x10]
 L000b: mov r8d, [rax+8]
 // Check that array length >5
 L000f: cmp r8d, 5
 L0013: jbe short L0034
 L0015: movzx r9d, byte ptr [rax+0x15]
 L001a: add edx, r9d
 L001d: mov [rcx+0x10], edx
 // Check that array length is >6
 L0020: cmp r8d, 6
 L0024: jbe short L0034
 L0026: movzx eax, byte ptr [rax+0x16]
 L002a: add eax, edx
 L002c: mov [rcx+0x10], eax
 L002f: add rsp, 0x28
 L0033: ret
 // throw IndexOutOfRangeException
 L0034: call 0x00007ff8b097f6a0
 L0039: int3
But if we flip them around and check the highest number first, the compiler understands that there is no need to check the lower numbers.
using System;
public class Arrays {
 public byte[] PublicArray = new byte[10];
 public int Sum = 0;

 public void IndexedAccess()
 {
 var pa = PublicArray;
 Sum += pa[6];
 Sum += pa[5];
 }
}
Results in only one bounds check:
L0000: sub rsp, 0x28
 L0004: mov rax, [rcx+8]
 L0008: mov edx, [rcx+0x10]
 L000b: mov r8d, [rax+8]
 // Check that array length is >6
 L000f: cmp r8d, 6
 L0013: jbe short L002e
 L0015: movzx r8d, byte ptr [rax+0x16]
 L001a: add edx, r8d
 L001d: mov [rcx+0x10], edx
 L0020: movzx eax, byte ptr [rax+0x15]
 L0024: add eax, edx
 L0026: mov [rcx+0x10], eax
 L0029: add rsp, 0x28
 L002d: ret
 // throw IndexOutOfRangeException
 L002e: call 0x00007ff8b097f6a0
 L0033: int3